
Overview
Arena: AI Model Ranking
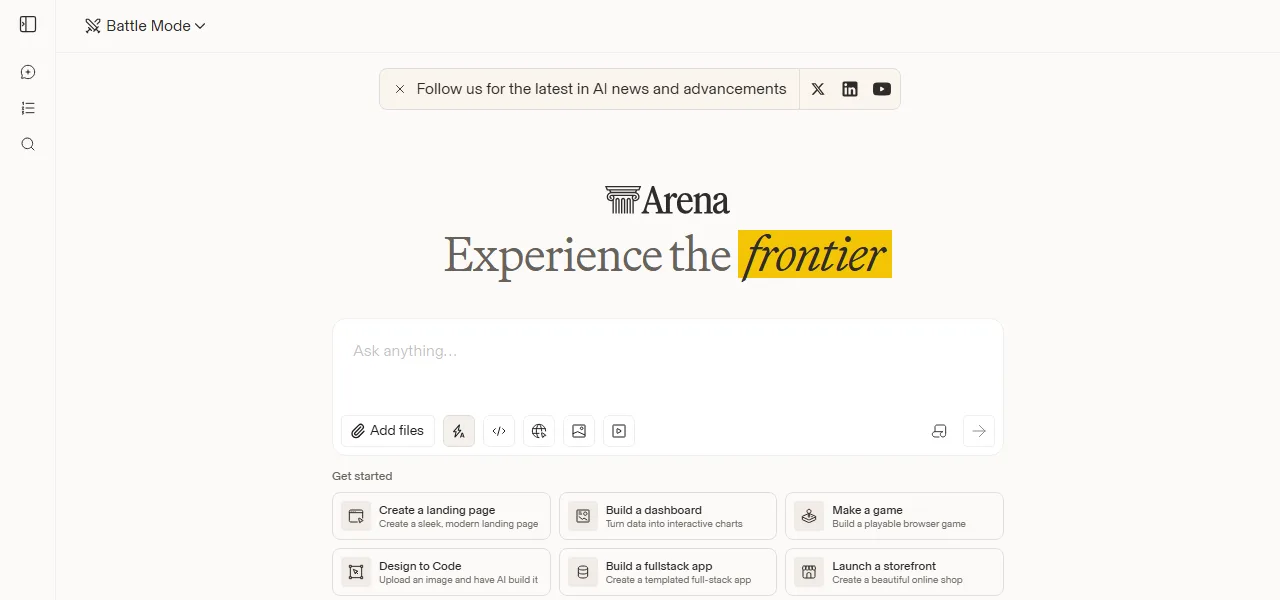
Designers and developers seeking to evaluate and implement top-tier language and generative models can leverage Arena to test AI performance in real time. The platform features an interactive chat leaderboard, blind battle mode, and side-by-side model comparison tools that rank leading LLMs, image generators, and coding assistants based on human preferences. Users participate directly by submitting prompts, voting on response quality, and observing model strengths in unbiased direct competitions. Beyond model evaluation, Arena allows creators to transform simple text inputs and uploaded images into functional application designs, playable browser games, and customized full-stack templates using connected AI providers. By leveraging crowdsourced feedback and human-in-the-loop testing, the benchmark offers transparent performance metrics across diverse tasks. While the system provides robust public leaderboards and blind testing capabilities, it currently lacks extensive enterprise-grade analytics for tracking private benchmark runs over extended periods. Overall, Arena serves as a essential hub for community-driven artificial intelligence evaluation, helping developers, researchers, and creators select the optimal foundational models for their specific technical applications and interactive software deployment needs.