
Overview
Cerebras AI: Wafer-Scale Engine hardware
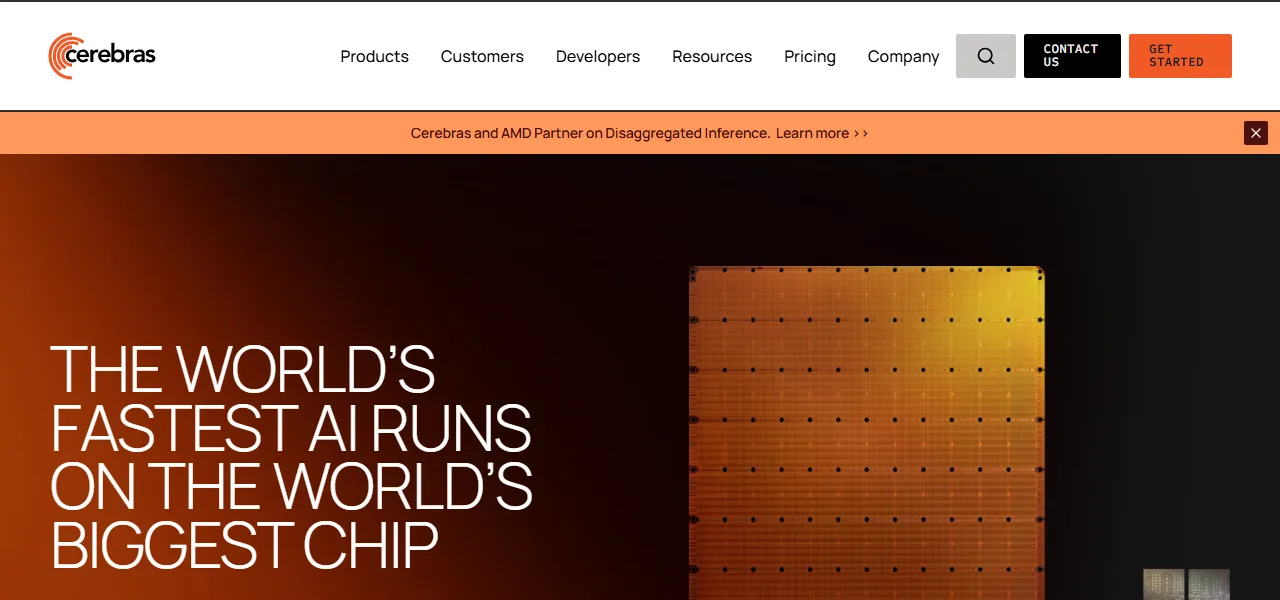
Cerebras AI provides high-performance hardware and cloud infrastructure designed specifically to accelerate deep learning training and high-throughput inference tasks. Powered by the proprietary Wafer-Scale Engine, the platform delivers massive parallel processing capabilities, bypasses conventional GPU memory bandwidth bottlenecks, and drastically cuts iteration cycles for complex neural network architectures. Developers can deploy frontier foundation models, execute real-time token generation, and process massive contextual prefill tasks through a unified API compatible with standard machine learning frameworks. The infrastructure supports disaggregated inference, enabling high concurrency and low latency across enterprise workloads without requiring manual cluster orchestration. Strategic integrations with hardware ecosystems allow seamless scaling across high-density compute facilities. While the underlying architecture achieves industry-leading throughput for large language models and computer vision systems, the platform relies on specialized physical hardware, which limits hyper-custom low-level kernel modifications compared to standard general-purpose GPU setups. Cerebras offers an essential foundation for organizations building, fine-tuning, and serving generative intelligence at scale.