
Overview
Imagen: Text-to-image diffusion
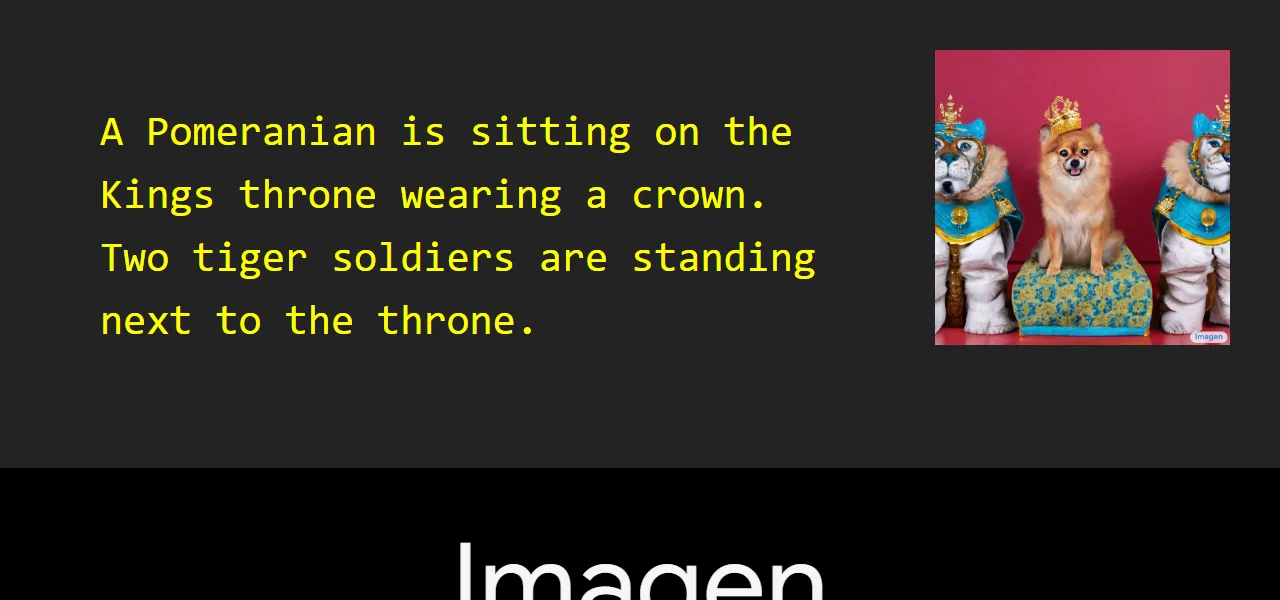
Google Research developed Imagen as a text-to-image diffusion model capable of synthesizing detailed photorealistic images from written prompts. Built upon large transformer language models like T5, Imagen processes text prompts to understand context, spatial relationships, and artistic style before generating high-resolution outputs. The architecture relies on frozen text encoders paired with cascaded diffusion models that iteratively refine image details from low-resolution drafts to crisp visual outputs. By evaluating image-text alignment against standard industry benchmarks, Imagen demonstrates fidelity across diverse prompt styles, including complex objects, abstract artistic renderings, and real-world scenes. The system allows researchers and creators to experiment with synthetic visual generation, text prompt conditioning, and spatial layout interpretation without manual image manipulation. While the underlying model requires substantial computational resources to run and fine-tune locally, its architectural approach has set new standards for conditional image generation. Imagen continues to serve as a foundation for advanced generative research, supporting downstream image editing workflows, video generation models, and interactive visual synthesis applications across creative software platforms.