
Overview
vLLM: High-throughput inference engine
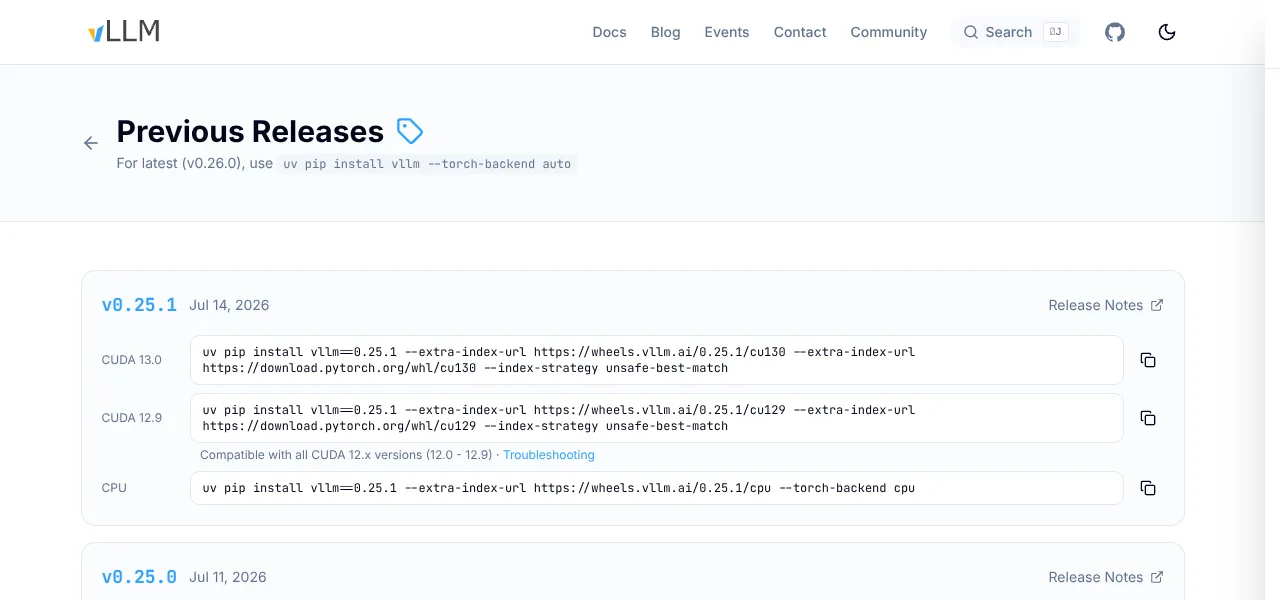
vLLM is an open-source, high-throughput, and memory-efficient inference engine designed for serving large language models effectively across diverse hardware platforms. By leveraging advanced memory management techniques like PagedAttention alongside continuous batching, the framework optimizes GPU memory allocation to drastically reduce latency and maximize overall hardware utilization. It provides full compatibility with standard OpenAI API endpoints, allowing developers to integrate open-source models directly into existing application workflows without heavy code refactoring. Designed to support multiple compute backends including CUDA, ROCm, Intel XPU, and standard CPUs, vLLM scales seamlessly from single-node setups to distributed enterprise environments. The ecosystem is optimized for modern Python environments and offers streamlined installation pipelines to simplify setup across development and production servers. Through efficient hardware execution, software engineering teams can significantly decrease operational infrastructure costs while sustaining high request throughput for demanding generative artificial intelligence workloads. Detailed documentation and active open-source community support further streamline deployment, troubleshooting, and continuous performance tuning for production environments.